Rerun

Manage Incidents and Write Postmortems

Triage alerts into a first diagnosis, coordinate the response and on-call, and turn every incident into a blameless postmortem with owned fixes.

Manage Incidents and Write Postmortems agent board

About

Get through production incidents with less chaos, and make sure the same one does not come back.

What it does

  • Turns alerts into a first diagnosis for the on-call person: what is failing, impact, likely severity, evidence, first checks
  • Groups related alerts, drafts the incident kickoff, pages and status updates
  • Looks for what changed (deploys, config, traffic) to point at the likely cause
  • Posts a daily on-call briefing: who is on call, open incidents, overdue follow-ups
  • Writes blameless postmortems with a sourced timeline, root cause and owned action items
  • Finds recurring causes and open actions across past incidents

What you need

  • Nothing to start: paste an incident thread or try it on a sample incident
  • PagerDuty, to read alerts, incidents and the on-call schedule and page responders
  • Slack, to read incident channels and post updates (Opsgenie, Teams or another tool can be connected instead)

How setup works

A postmortem arrives in the first minutes. Along the way it learns your severity levels, services and owners, connects PagerDuty and Slack, triages a real alert and confirms the daily briefing.

What stays in your hands

  • It drafts pages, announcements and tickets and sends them only with your go-ahead; the daily briefing is the one message it posts on its own, once you approve it

What you will need

  • PagerDuty

  • Slack

Coworkers in this template

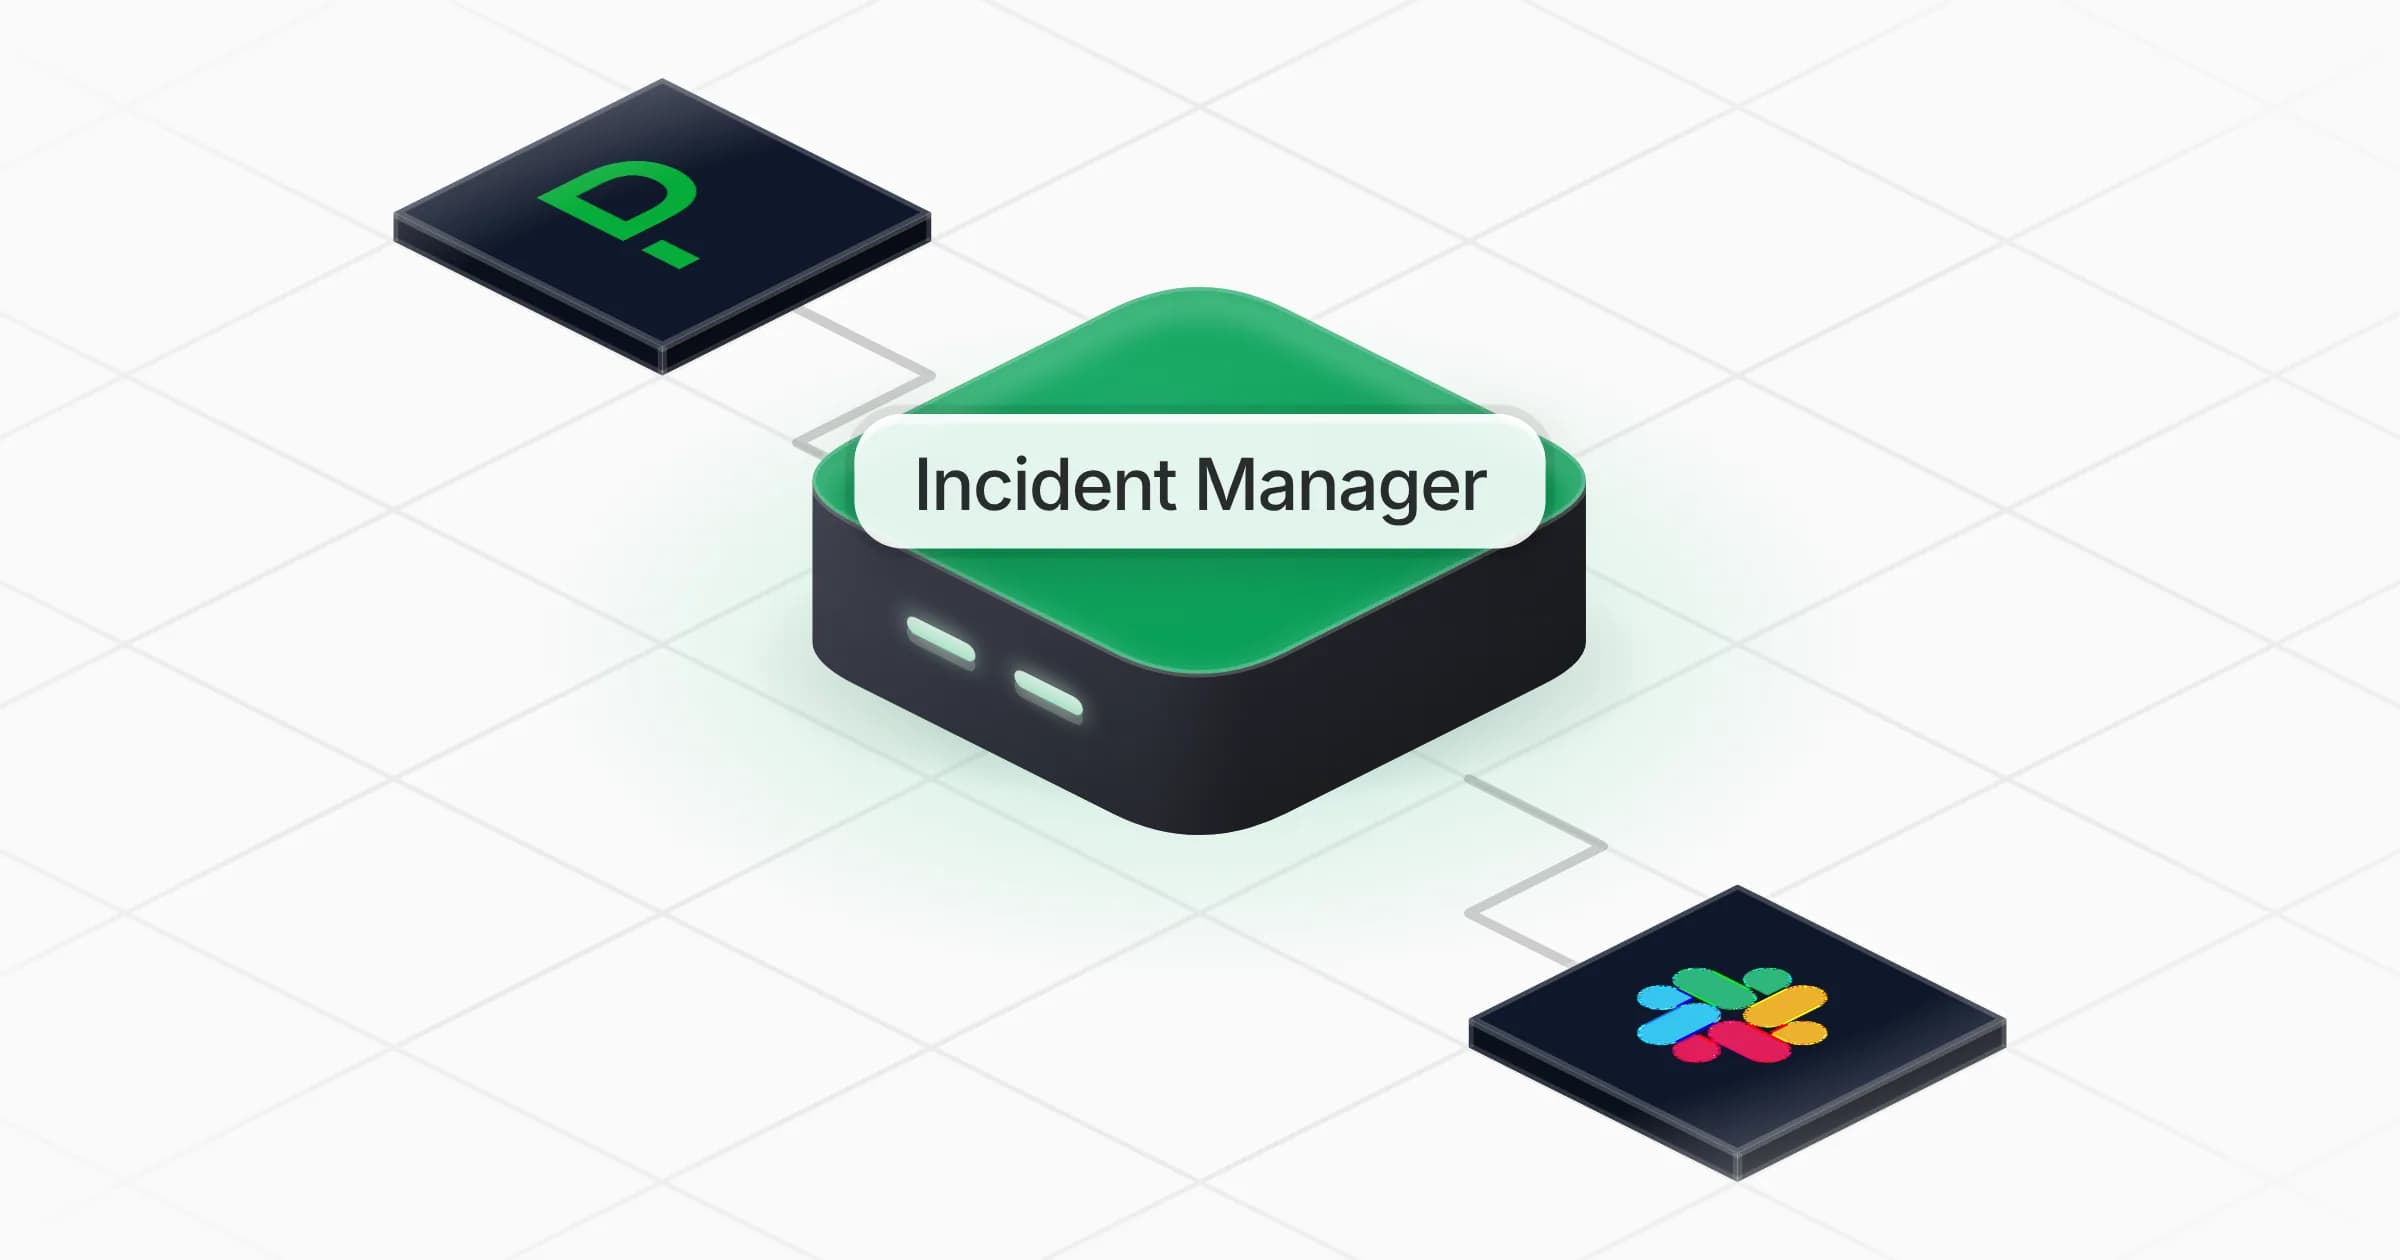
Incident Manager

Triages alerts, coordinates the response and writes blameless postmortems that turn incidents into fixes.

Apps

Skills · 6

Announce who is on call

Use when asked who is on call, to share the on-call rota or a handover, and on the daily on-call briefing.

Diagnose a production issue

Use when asked why something is failing in production, to debug a crash or error from logs and traces, or to find the change that caused it.

Find the recurring causes

Use when asked what keeps breaking, to review past incidents or postmortems for patterns, or to check which follow-up actions are still open.

Start the incident response

Use when an incident is declared or should be, or when asked to page responders, open an incident channel or write a status update.

+2 more

Scheduled tasks · 1

Daily on-call briefing

At 09:00 AM, Monday through Friday
Frequently asked questions

Can it write a postmortem from a Slack thread?

Yes. Paste the thread or connect Slack, and it rebuilds the timeline with sources, the impact, the root cause, contributing factors and owned action items.

Does it page people on its own?

No. It drafts the page and the kickoff message with the right responders and sends them when you say go.

Does it work with Opsgenie or incident.io instead of PagerDuty?

It works from whatever you paste, and offers the tools you use from the Rerun catalogue when they are available.

Are the postmortems really blameless?

Yes. Causes are written as conditions in the system and process, and people appear only as roles in the timeline.

Can it find recurring causes across incidents?

Every postmortem is saved with its causes and actions, so it can group past incidents by cause and service and show which fixes are still open.

How much does it cost to run?

The template is free. Each run uses Rerun credit, like any coworker.

2,000+ businesses run on Rerun

Hire Coworkers on the ChatGPTplan you already pay for.

  • 1. Plug in your subscription
  • 2. Set up your Coworkers
  • 3. Run your business with Coworkers